Annotations
Compose your own semantic ranges into the Lumis event stream and render them from a custom formatter.
An annotation is a source range you supply, carrying data Lumis never inspects. Lumis composes those ranges with the syntax events for one highlighting operation, and a custom formatter decides how to render them.
Use them for overlays that are not syntax: diff hunks, search matches, diagnostics, coverage, blame.
Lumis does not compute the ranges. A diff library, a search index or a compiler supplies them; Lumis only places them correctly relative to the syntax.
Building annotations
A range is either absolute offsets in UTF-8 bytes, or zero-based lines with UTF-8 byte columns. Both are half-open, and both are rejected if they fall outside the source or land inside a character.
An empty range is a point: it marks a position rather than covering text,
and the formatter gets AnnotationStart immediately followed by
AnnotationEnd there. Line-based views need this, because a blank line has
nothing to cover and is still somewhere a review comment can land. Only a range
that runs backwards is rejected.
A point has no interior, so it does not split the syntax scope it falls in — unlike a range, which closes and reopens one. A point at a range's start nests inside it; a point where a range ends falls outside it, following the same half-open rule as everything else.
A position column counts bytes within the line, and a CRLF line keeps its
\r, so measure the line before splitting the terminator off or the last
character falls outside the range.
const annotations = [
  {
    range: {type: 'offset', start: 12, end: 23},
    data: {change: 'added'},
  },
  {
    range: {
      type: 'position',
      start: {line: 1, column: 10},
      end: {line: 1, column: 21},
    },
    data: {change: 'removed'},
  },
]

const html = hl.highlight(source, formatter, {annotations})
Rendering them
A formatter receives two events beyond the syntax ones: an annotation opens and an annotation closes. The opening event carries your data, and the range resolved to byte offsets whichever form you built it from.
The closing event carries no payload, so a formatter that renders more than one kind of annotation keeps a stack of what it opened.
import type {Formatter, HighlightEvent} from '@lumis-sh/lumis/formatters'

const formatter: Formatter<Change> = {
  language: javascript,
  render(source, events) {
    const bytes = new TextEncoder().encode(source)
    const decoder = new TextDecoder()
    const open: string[] = []
    const out: string[] = []

    for (const event of events) {
      if (event.type === 'annotationStart') {
        const tag = event.data.change === 'added' ? 'ins' : 'del'
        out.push(`<${tag}>`)
        open.push(tag)
      } else if (event.type === 'annotationEnd') {
        out.push(`</${open.pop()}>`)
      } else if (event.type === 'source') {
        out.push(decoder.decode(bytes.subarray(event.start, event.end)))
      }
      // 'start' and 'end' carry the syntax scopes
    }

    return out.join('')
  },
}
Annotations are the outer layer
When an annotation begins or ends inside a syntax scope, Lumis closes that scope and reopens it, so the stream a formatter sees is always properly nested rather than overlapping.
Annotating only rice inside the identifier price splits the surrounding
variable scope in two:
<span class="l-variable">p</span><ins><span class="l-variable">rice</span></ins>
That means a formatter never has to reconcile crossing ranges, and can emit tags as it goes.
Annotations nest against each other the same way. Two that overlap without
containing one another leave the inner one closed and reopened around the
outer one's end, so one annotation can produce more than one
AnnotationStart. A formatter that opens a tag per start is correct; one that
records something once per annotation should key on the annotation rather than
count the events.
Built-in formatters ignore annotations
html_inline, html_linked, html_multi_themes, terminal and
bbcode_scoped skip annotation events, because they cannot know how to render
data they have never seen. Annotations are for custom formatters.
Complete examples
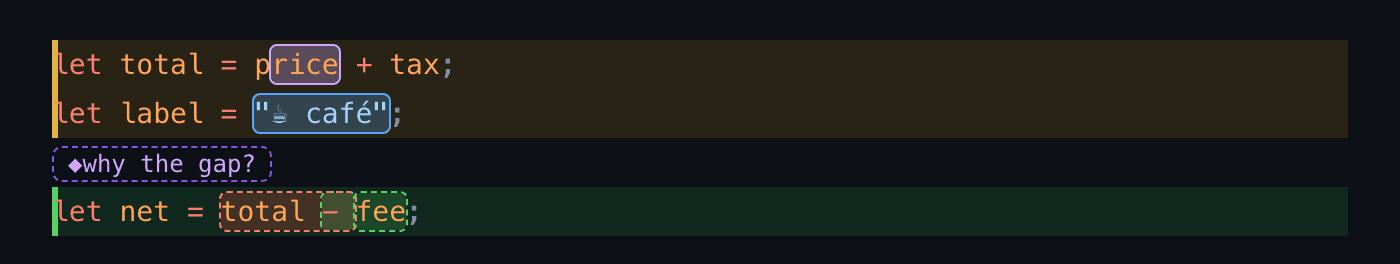
Each runtime ships one runnable example over the same four-line source, where every annotation demonstrates a different case: a position range crossing a line boundary, an offset range starting mid-token so a syntax scope splits, a multibyte literal, a point on a blank line, and two annotations that overlap without nesting. All three print the same output.
| Runtime | Example |
|---|---|
| JavaScript | examples/annotations.ts |
| Rust | examples/annotations.rs |
| Elixir | examples/annotations.exs |
Styled, the output shows each case: the amber and green bars are whole-line
position ranges, rice is outlined on its own because the annotation split the
variable scope around it, the string literal is covered by byte offsets over
multibyte characters, why the gap? is a point on a blank line, and the last
line carries two annotations that overlap without nesting.